In the last blog we looked at the phenomenon of “jagged intelligence” — the paradox that AIs are simultaneously superhuman and stupid in adjacent skills. We identified a lack of continual, fast learning and embodiment as possible causes of this weirdness, and noted that embodiment is also a “learning problem”, because current ML models can’t learn from a single thread of experience. So continual, fast learning became the focus of our attention.
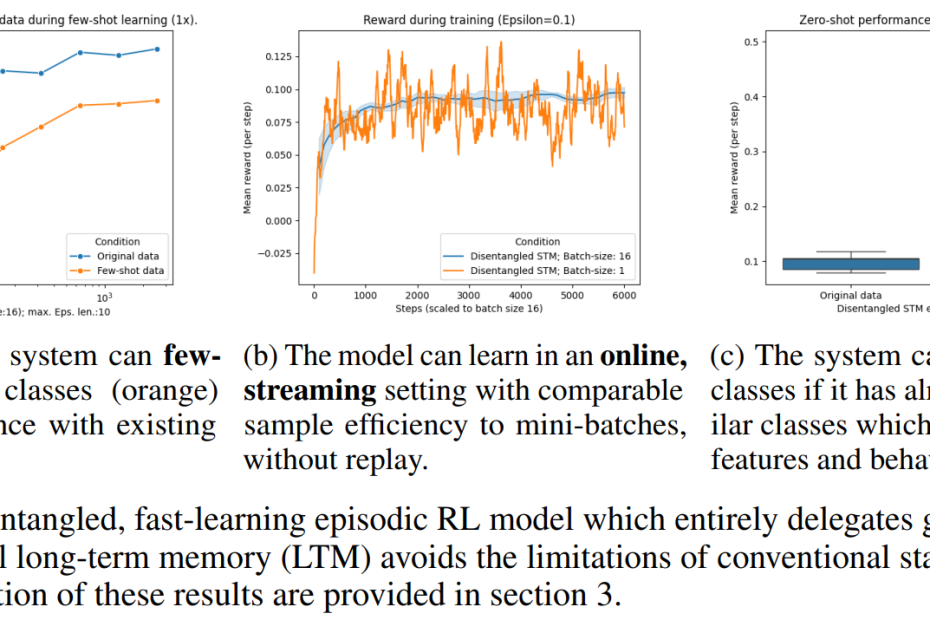
This month we have some exciting progress to announce, which potentially opens a path to resolving these issues. In a recent paper, we explored what would happen if you completely abandoned generalization in a fast learning system.
Under these conditions, it’s surprisingly easy to achieve fast learning without interference with existing memories — we demonstrated continual zero-shot, few-shot and even streaming RL on a toy dataset. (In streaming RL, you must learn immediately from samples from a single thread of experience in the environment, mimicking the conditions of an embodied agent or a mobile robot).
This article will recap the core ideas and also explain our next step, which will be an established one-shot / few-shot ML benchmark.
The core idea
The core idea: stop forcing fast learners to generalize. Just accept that fast learning and generalization are essentially contradictory requirements.
But !— I hear you say — real-world data has variance, noise and uncertainty. If the system can’t generalize, how can this be overcome?
The answer is that although the system needs to generalize, that doesn’t mean every component of the system needs to. Generalization could be delegated to a “perception” component:
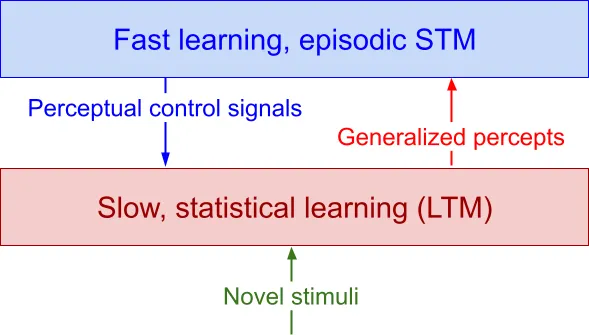
The proposed system has two parts: A fast-learning, non-generalizing Short Term Memory (STM) and a slow-learning, generalizing Long-Term Memory (LTM). This is inspired by an existing theory called Complementary Learning Systems, but with a twist. Instead of viewing the STM as a helper for the LTM, to help it learn quickly, the STM in our system is the actor which decides policy — i.e. what action to take. The LTM is relegated to simply being an interpreter, who can abstract input data into concepts the STM already understands and are relevant to the task.
The blind spot
Machine learning rightly considers generalization to be a vital property for systems to function on real data. But that perspective might have been taken too far, because researchers have spent decades chasing a fast-learning system which also generalizes, without definitive success.
By giving up generalization and just generalizing inputs, our STM can learn very quickly and can learn about the specifics of individuals and situations. This is potentially game-changing for robotics, where the variety of real-world conditions has limited robots to repetitive tasks in controlled environments.
New experimental results
As a first proof-of-concept for the system we used a pretrained Large Language Model (LLM) to generate a stream of “encounters” for a Reinforcement Learning (RL) agent. Each encounter is based on the theme of a mouse, who encounters various animals, plants and people. It’s a bit like “Dungeons and Dragons”!
The agent can do one of the following things:
- Observe and think about the object it has encountered
- Try to approach the object
- Try to eat the object
- Run away
- Hide
Active perception system
The LLM also acts as the LTM for our agent. If the agent decides to observe the object it can ask the LLM about the observable qualities of the object — for example, “is it bigger than me?” [the mouse]. The LLM is encouraged to give simple yes/no answers, which are provided to the STM / agent. The agent can’t ask the actual class of the object, which isn’t observable.
Environmental dynamics
For convenience (but not as part of its role as LTM), the LLM also implements the environment dynamics. This decides what happens when the agent decides to do something. For example, if the object is a cat, and the mouse decides to run away, we ask the LLM if the cat will eat the mouse. If it does, the mouse gets a reward of -1. The LLM has a relatively high temperature, which means its answers have some uncertainty.
Few-shot learning
In this experiment we trained our agent on a modest dataset of encounters which excluded some types of object, specifically “fly agaric mushrooms” and “deadly nightshade” (and tomatoes and radishes, otherwise it will start learning to avoid all red plant-based food because it correctly learns they’re all poisonous).
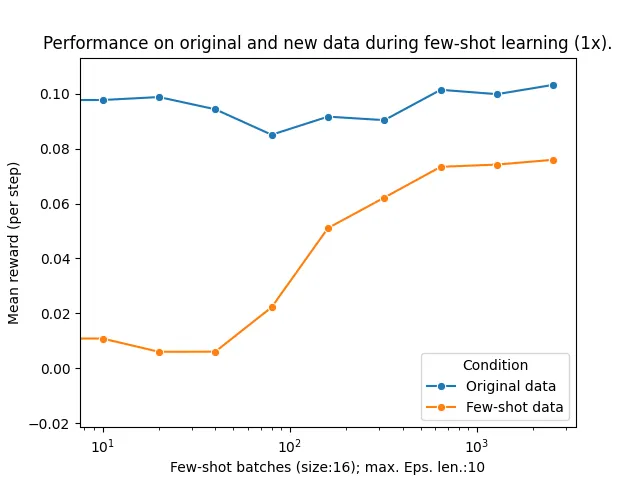
The few-shot phase begins when we stop training the agent on all the other encounters and start training it on the excluded classes of poisonous plants. After each few additional exposures we evaluate the agent on:
- The original training data — to make sure it hasn’t forgotten how to handle those encounters — so-called “catastrophic forgetting”
- The new data — to see if it has learned to handle those encounters
We found that the agent was able to rapidly learn to handle the new encounters with no effect on its memory of how to handle the original encounters (see plot below):
Baseline model
For comparison, we also evaluated a conventional feed-forward, 2-layer neural network in exactly the same conditions. The conventional neural network suffered a significant loss of performance on the original data even before completely learning how to handle the new data.
These results were not surprising. Since conventional stochastic gradient descent training of neural networks leads to entangled representations, any new memories being learned interfere with existing memories, leading to a drop in performance on the original encounters.
Code for all the models, experiments and results analysis is available on Github.
Streaming RL
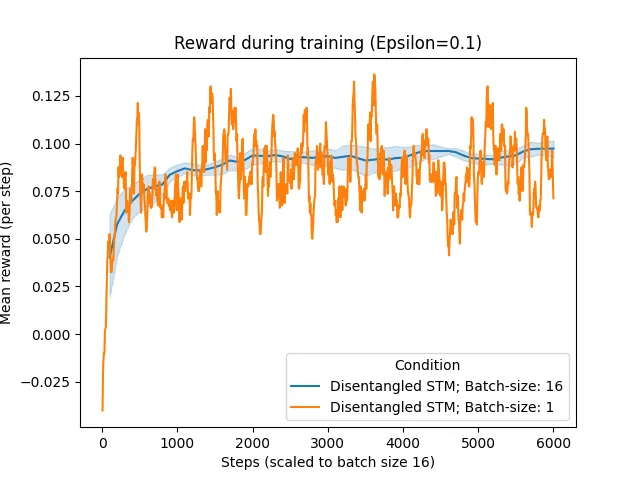
We also tested the system in a streaming-learning setting. This means that the model must immediately update after each step and cannot use replay buffers or back-propagation through time to associate actions with delayed rewards. It can’t sample from multiple environments simultaneously. As shown in the plot below, our model achieves the same performance regardless whether it is trained with minibatch stochastic gradient descent or with a batch size of 1 — effectively a single continuous experience.
Not only that, but the sample efficiency is identical in both settings — the same number of exposures to the data is required whether training in streaming or mini-batch mode.
Zero-shot learning
Zero shot learning means to perform some inference or reasoning about a specific class of objects which have never previously been encountered. This is usually achieved by generalization or extrapolation from existing data.
Since our proposed perceptual system describes new objects or encounters in terms of their observable attributes, it can zero-shot new classes which share some attributes with known classes.
For example, our dataset includes encounters with harmless birds (such as pigeons and sparrows) and predatory birds (such as hawks, falcons and eagles). Since the agent doesn’t know the class of the animal it encounters, it asks a series of perceptual questions about it such as — “can it fly?”, “does it have a long tail?” or “is it looking at me?”. Some of these questions reveal task-relevant clues as to the identity of the animal. Others are irrelevant. Some answers are consistent, and some are unreliable. The agent utilises this sequence of observations to decide what to do.
It is somewhat obvious then that the agent will know how to react to a novel animal which shares characteristics with ones it has encountered before. We decided to confirm this anyway, by withholding Eagles and Falcons from the training data but including Hawks. As expected, the mouse-agent immediately responds to eagles by hiding. Zero shot!
Planned experiments
Our results are exciting, but preliminary. The biggest weakness is the simplicity of the experiments completed so far. Although there is uncertainty in the LLM answers about each encounter, there is no spatial or visual variance to deal with. In addition, it’s a toy problem designed to fit the proposed architecture (you have to start somewhere!)
Our next steps will be to apply the proposed architecture to some established benchmarks.
Omniglot
https://github.com/brendenlake/omniglot
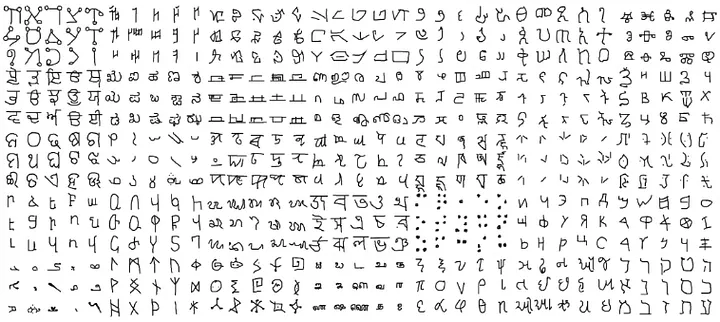
The first benchmark we will attempt is Omniglot. This dataset is similar to MNIST in having one centred character-glyph in each image. There are two popular versions of the challenge — one-shot, and few-shot.
Unlike most datasets which contain many samples of a few classes (MNIST has 60,000 samples of the digits 1–10), Omniglot has just a few samples of many languages.
The benchmark is considered solved, with methods such as memory-augmented neural networks (MANN) achieving superhuman performance. However, it’s still a good first challenge for a novel method, which needs to be developed through tasks of gradually increasing difficulty. It does require the method to overcome spatial / appearance variation in one-shot and few-shot settings.
ARC-AGI-3
https://arcprize.org/arc-agi/3
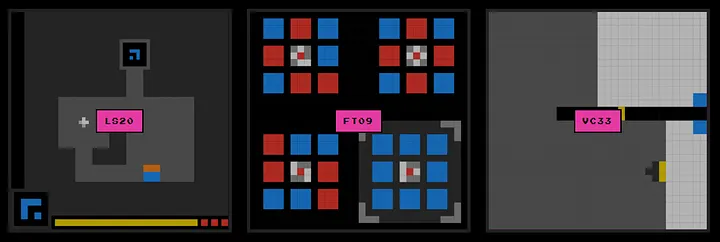
The new ARC-AGI-3 benchmark is quite different to the first two versions, which required drawing pixels in 2d grids. The new benchmark is a set of different computer games which the player learns by playing. Each game has different rules, which are introduced over time.
ARC-AGI-3 is surprisingly well suited to our architecture because it’s inherently episodic and only provides a reward signal at game completion, rather than a supervised target for each output.
Our aim isn’t necessarily to achieve the highest score on this benchmark. We’ll be competing against LLM-based AIs backed by hundreds of billions of dollars of investment. If a tiny model trained on a single CPU can be remotely competitive, it will be a really successful result.
Summary
We think we’re on an interesting line of investigation with these early results. If it scales, this will lead to a really different kind of AI, which embodies Kahneman’s System 2 mode of thought — slow, deliberate, and conscious. Able to learn and reason about individual experiences here and now.
This is very different to the way LLM based inference works. In a recent presentation titled “Model collapse ends AI hype”, George Montañez says:
- LLMs don’t ponder, they process
- LLMs don’t reason, they rationalize
- LLMs don’t create endless information
I suspect the latter is a reference to the distinction between interpolation and generalization, rather than extrapolation. The model proposed in our paper can’t do anything but ponder — it must incrementally construct specific internal models for every decision, and requires a variable number of internal iterations before producing an external action.
If nothing else, we have successfully pursued the original idea of “what happens if you give up generalization in favour of fast learning” and found that the end isn’t as useless as you might expect!