Research · since 2026
Active perception
Can a fast episodic memory learn to steer a slow, generalising one, so that few-shot and continual learning work without forgetting?
How we got here
- 2026
- 2026
Project notes
Episodic looking (2026)
Generalising well and adapting continually pull against each other. A model that captures statistical regularities entangles its representations, so a large update driven by a few recent samples can overwrite what it knew. A model that stores samples separately avoids that, but cannot generalise. Our answer is a Complementary Learning System in which the fast learner does not need to generalise at all.
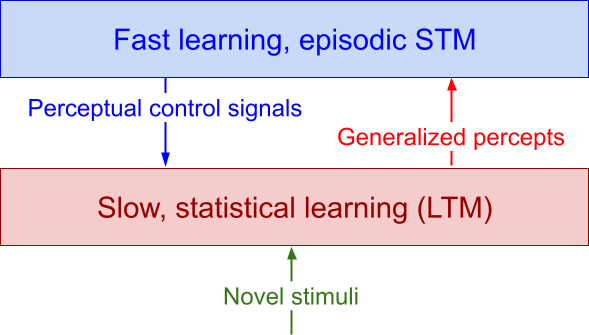
A short-term memory (STM) learns quickly and episodically. It gives up generalisation in exchange for learning without interference. A slow long-term memory (LTM) does the generalising, and the STM steers it through active perception, so that novel inputs come out described in terms the STM already understands.
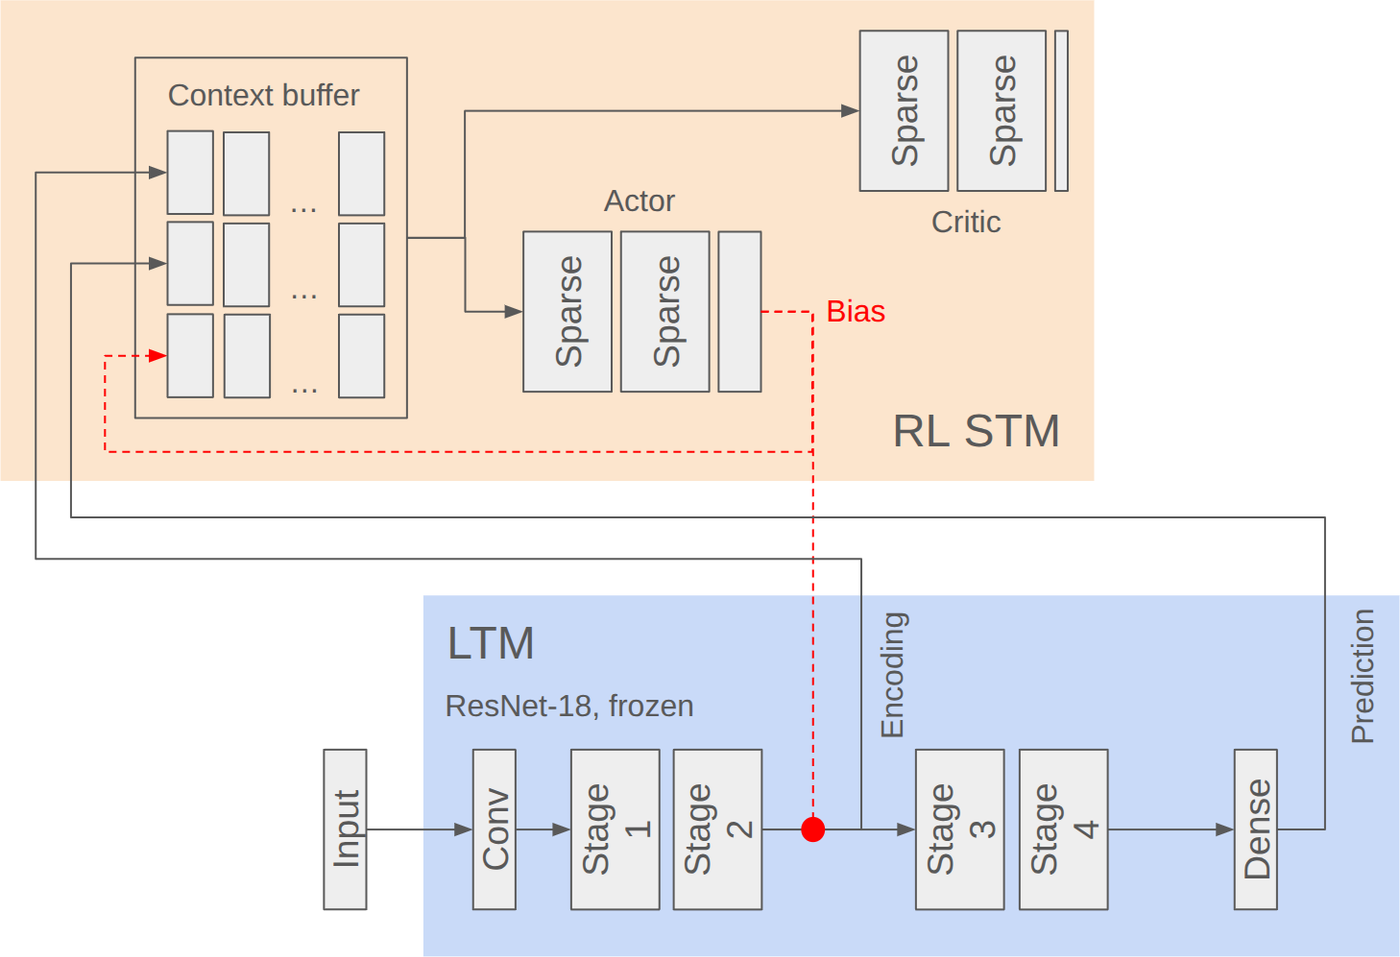
The STM is a reinforcement-learning agent. Its actor emits a multiplicative bias on the LTM's residual stream, and it is rewarded when that bias improves the LTM's classification. On image classification, the model resists forgetting better than a ResNet baseline in domain-incremental continual learning, and generalises better in few-shot learning than other continual learners. Its overall continual-learning accuracy is slightly lower than existing methods, which we attribute to limits in the LTM's representations and plasticity. Next, we will replay short-term memories to the long-term memory.
Results
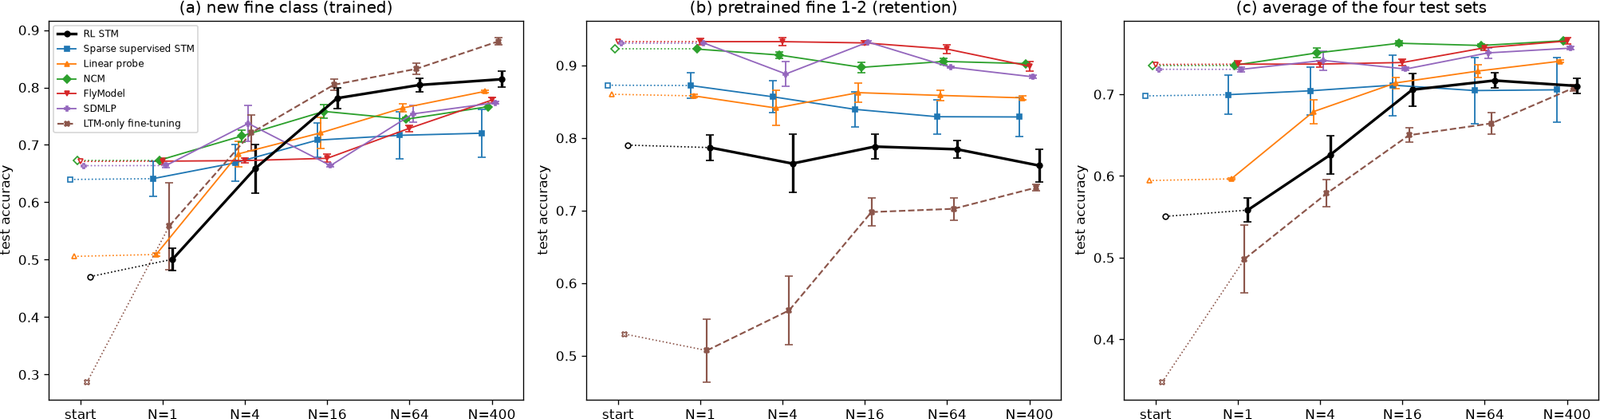
We compare the reinforcement-learning STM with other ways of building a fast learner on the same frozen features (a sparse supervised STM, a linear probe, nearest class mean, FlyModel and SDMLP), and with fine-tuning the long-term memory alone. In continual learning, fine-tuning the LTM alone learns the current class most fully but forgets heavily. The RL-STM learns less but forgets much less.
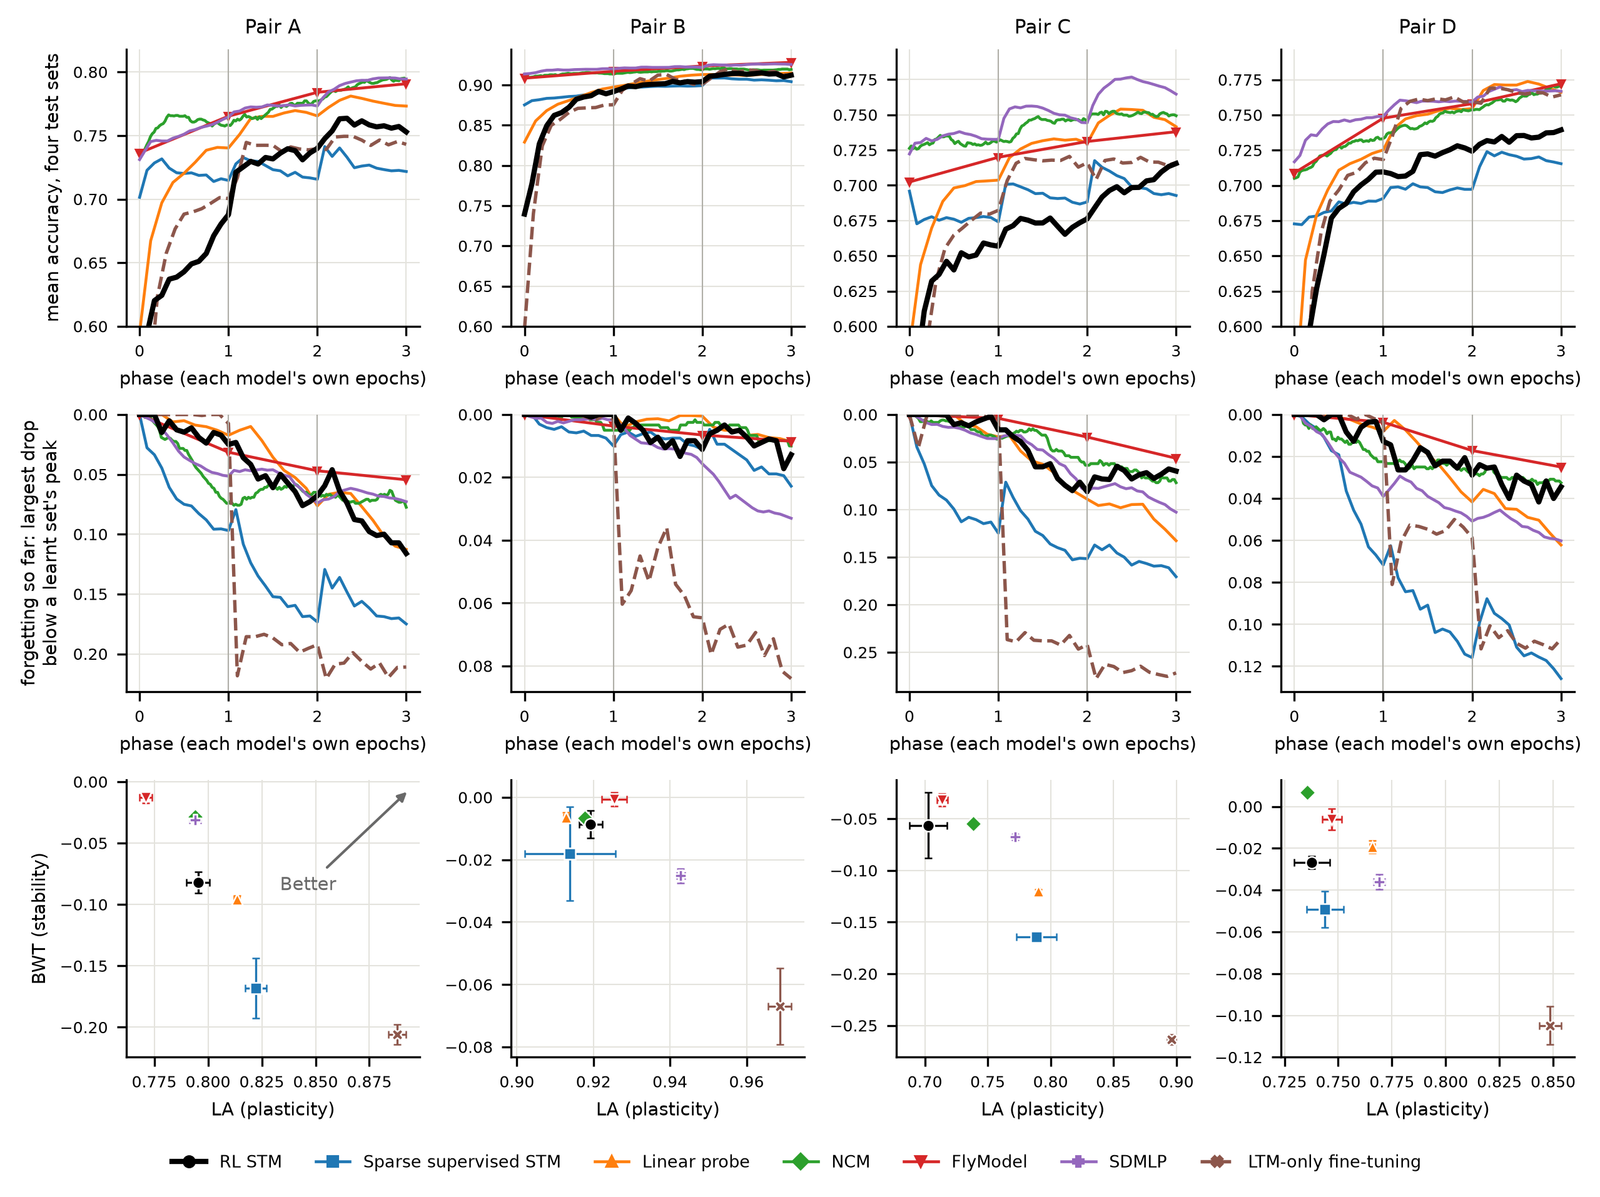
In few-shot learning, the RL-STM closes much of the gap to fine-tuning as examples are added, while keeping far more of what the long-term memory already knew.